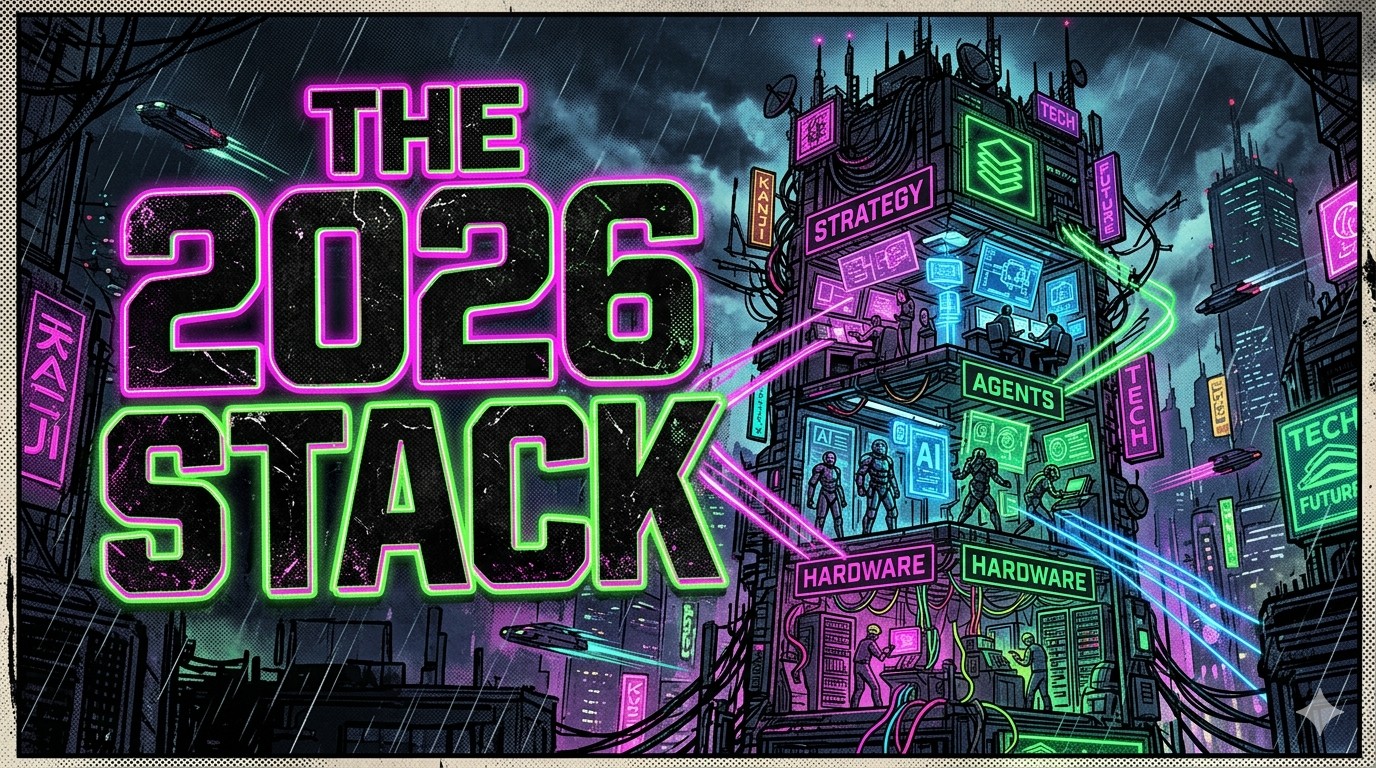
The 2026 Enterprise Stack: Integrating Hardware, Agents, and Strategy
The 2026 Enterprise AI Stack: a reference architecture linking hardware, inference engines, agentic orchestration, and governance into one vertically integrated system.
The 2026 Enterprise AI Stack: a reference architecture linking hardware, inference engines, agentic orchestration, and governance into one vertically integrated system.
Embedding caching for production: pair LRU semantic caching with incremental HDBScan for ultra-low latency real-time text clustering.
Tracking agent drift, security, and access control in real-time programmatic monitoring.
The fastest way to slash latency is right-sizing models for production classification.
The bottleneck for long-context agents is memory, not compute. Learn how to implement FP8 or INT8 KV caching to double your context length and survive inference at scale.
When a massive prompt stalls your entire inference server, you have a noisy neighbor problem. The solution requires rethinking how we process context with Chunked Prefill.