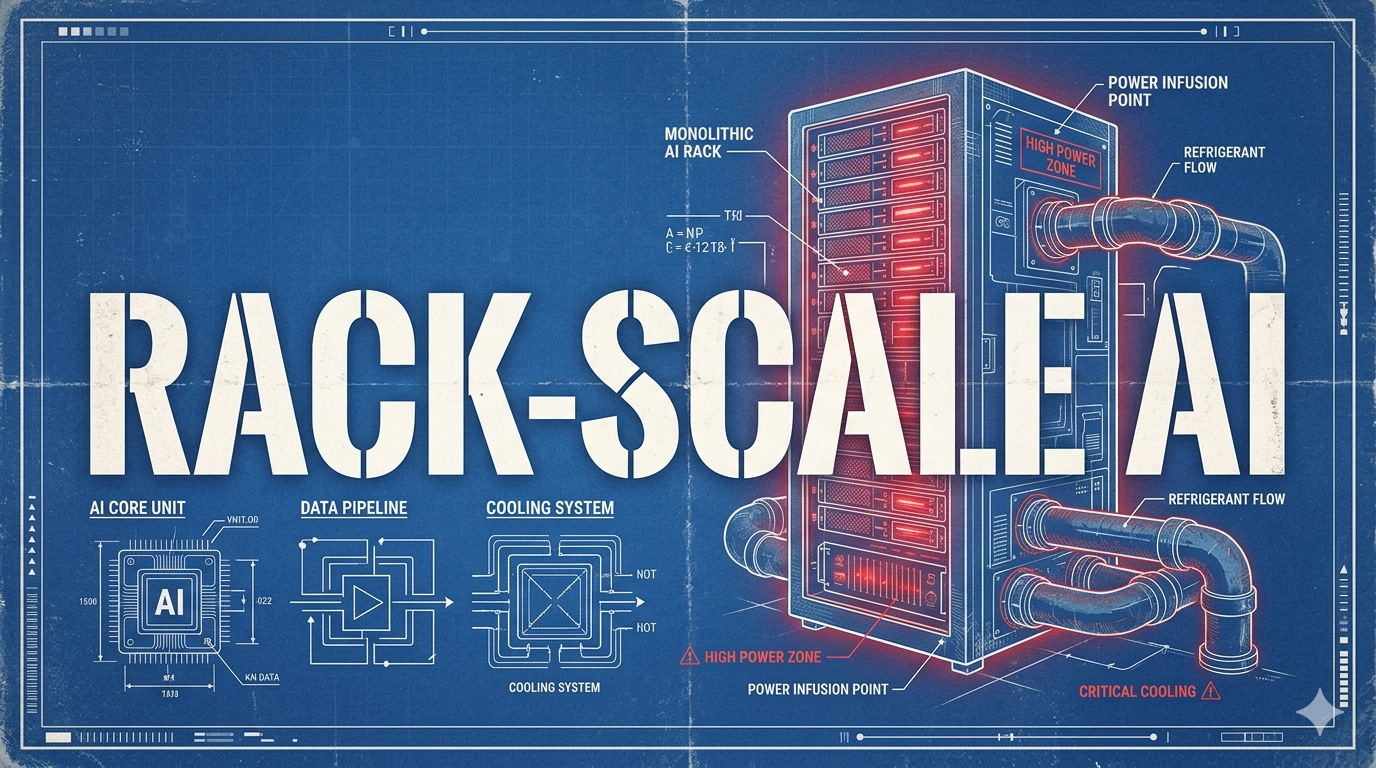
Rack-Scale AI Design: The End of Component Scaling
We have hit the physical limits of what a single chip can do. The new unit of compute for AI infrastructure isn't the GPU; it's the fully integrated rack.
We have hit the physical limits of what a single chip can do. The new unit of compute for AI infrastructure isn't the GPU; it's the fully integrated rack.
TTFT vs ITL explained: why Time to First Token matters more than average latency, and how to separate prefill vs decode.
Boards demand hard financial ROI over soft metrics like 'hours saved'. This is the framework to shift your AI strategy toward measurable margin and revenue impact.
RadixAttention in SGLang uses radix trees for KV cache optimization. Compare vs vLLM PagedAttention for multi-turn and agent workloads.
How to manage the shared state size in complex reasoning loops to prevent context window overflow without losing critical history.
As context windows scale to a million tokens, the KV cache becomes too large for GPU memory. The solution is a multi-tiered cache that offloads data to CPU and NVMe without killing latency.