· Strategy
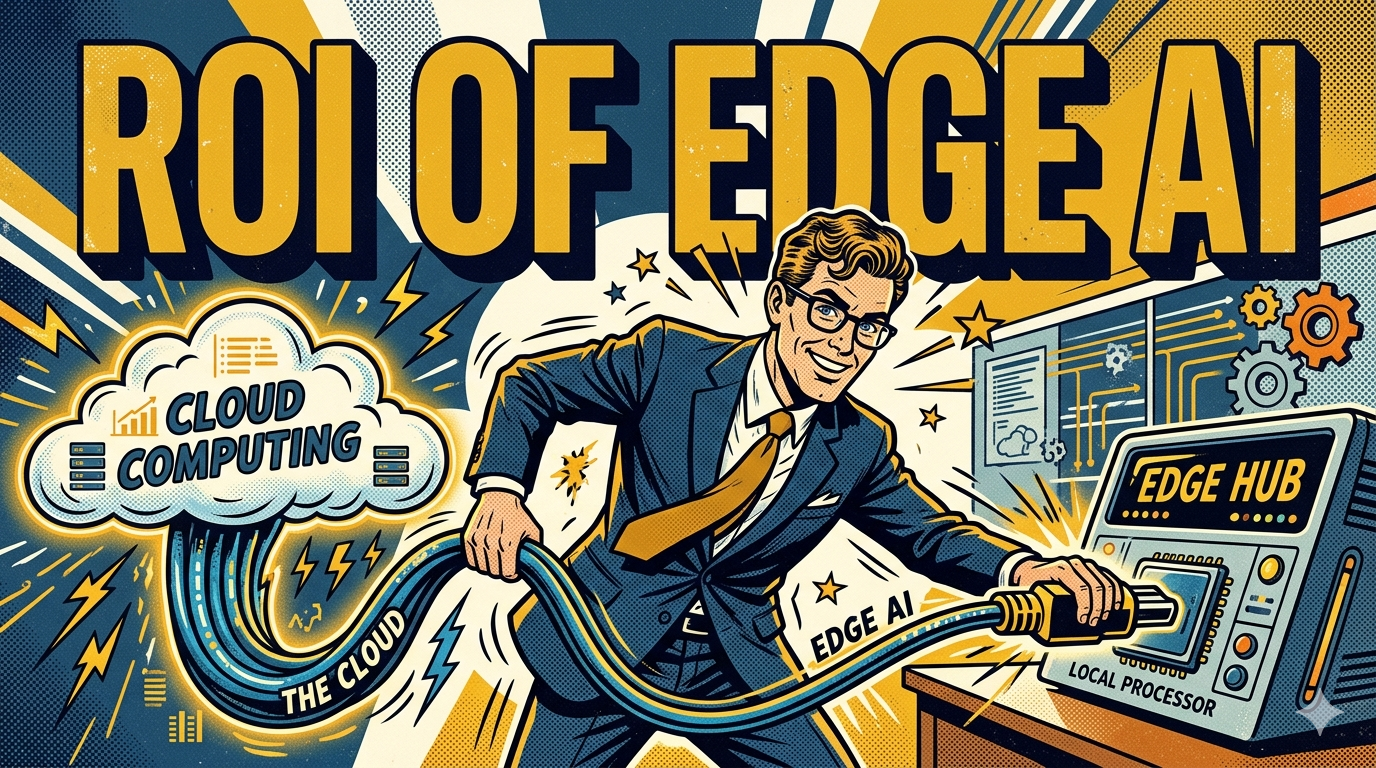
The ROI of Edge AI: Shifting Inference from Cloud to Prosumer Hardware
The economic case for deploying local LLMs to eliminate API costs and latency. Why relying entirely on cloud inference is a massive tax on your margins.
The economic case for deploying local LLMs to eliminate API costs and latency. Why relying entirely on cloud inference is a massive tax on your margins.
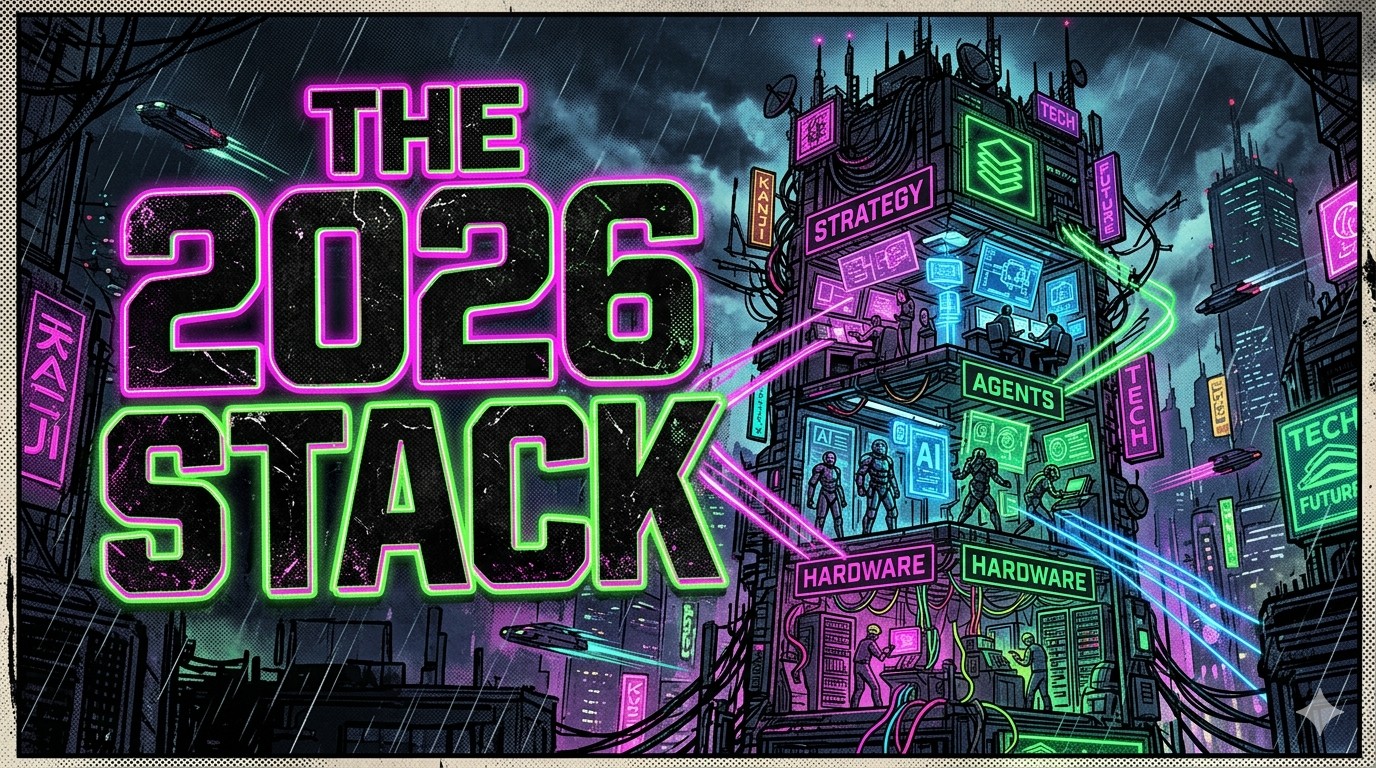
The 2026 Enterprise AI Stack: a reference architecture linking hardware, inference engines, agentic orchestration, and governance into one vertically integrated system.
Designing systems where humans provide strategic intent and override at checkpoints.
Analyzing the bottleneck of bulk clustering and using exact-match caching to reduce index compute load.
Embedding caching for production: pair LRU semantic caching with incremental HDBScan for ultra-low latency real-time text clustering.
Flipping the script on compliance to accelerate time-to-market by pre-clearing security.