Breaking the Bandwidth Wall: Why AI Clusters are Shifting to Ultra Ethernet
To scale past 100k GPUs, the industry is replacing proprietary InfiniBand with AI-optimized Ultra Ethernet.
To scale past 100k GPUs, the industry is replacing proprietary InfiniBand with AI-optimized Ultra Ethernet.
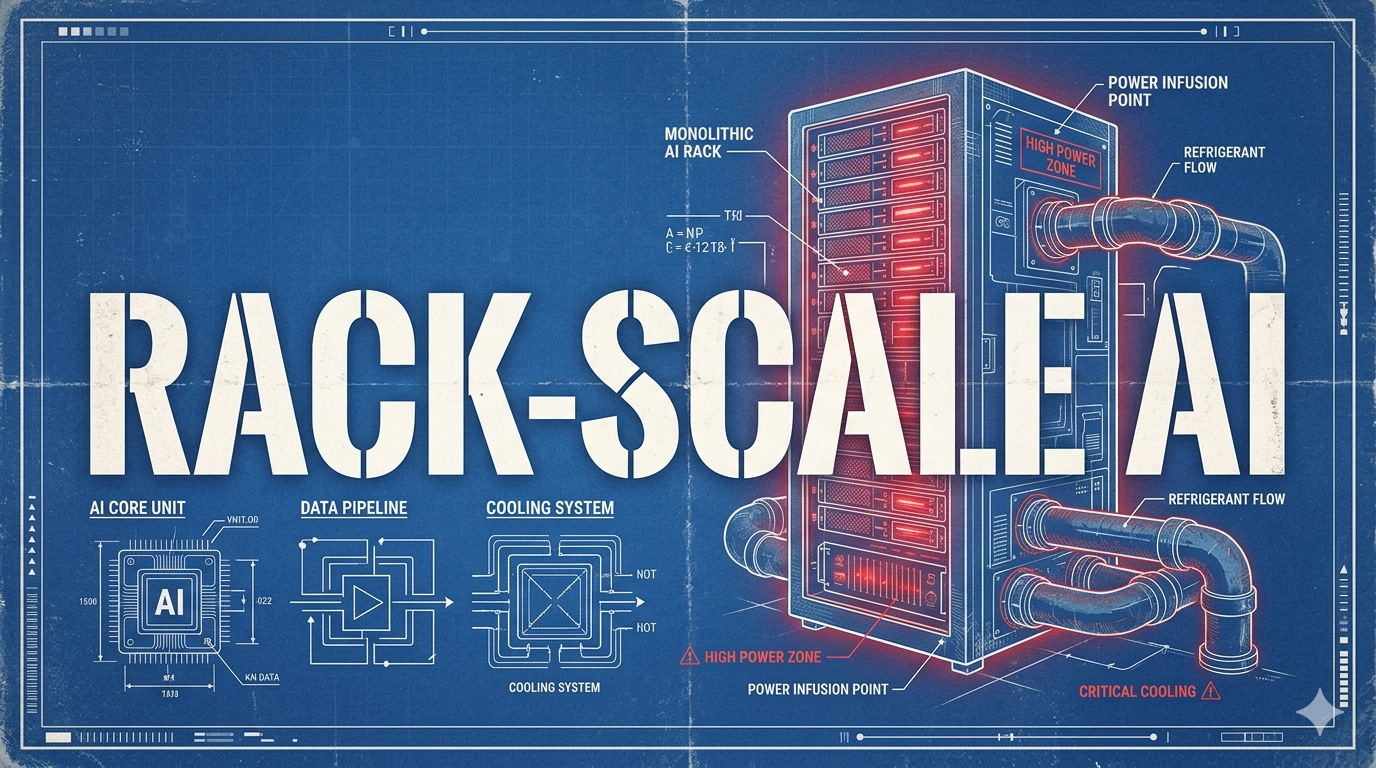
We have hit the physical limits of what a single chip can do. The new unit of compute for AI infrastructure isn't the GPU; it's the fully integrated rack.
JAX vs custom C++ AI training stack: why compiler-first JAX cuts data movement and improves throughput 2.7x for model training.